StreetSmart · Research Notes · Vol. I
A Compendium of Results, Refuted and Otherwise
Pieces of mathematics we have taken from the literature, restated in their own notation and tested on our own data. Each statement is followed by its empirical status, measured against an exposure-matched benchmark on held-out data after declaring the hypothesis in advance. Most of them failed. We keep the failures because they show where the edge is not.
§1The one problem
Every strategy we have examined reduces to one expression. It separates the four things a trader controls (direction, magnitude, cost, breadth) from the one thing they do not (volatility).
Let a bet win with probability p, move |r| in either direction, cost c per unit of turnover τ, and carry per-bet volatility σ. With BR bets per year of which a fraction f are effectively independent, the annualised Sharpe ratio and break-even hit rate are
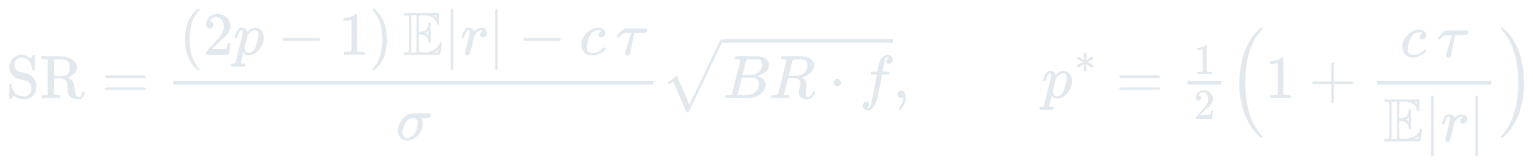
Remark. The square root is the law of large numbers. A 52.5% coin is worthless at one toss a year and very valuable at ten thousand, provided the tosses are independent. On our cross-sectional book, 27 nominal bets per rebalance behaved like about 20 independent ones.
§2Ornstein–Uhlenbeck and the optimal trading rule
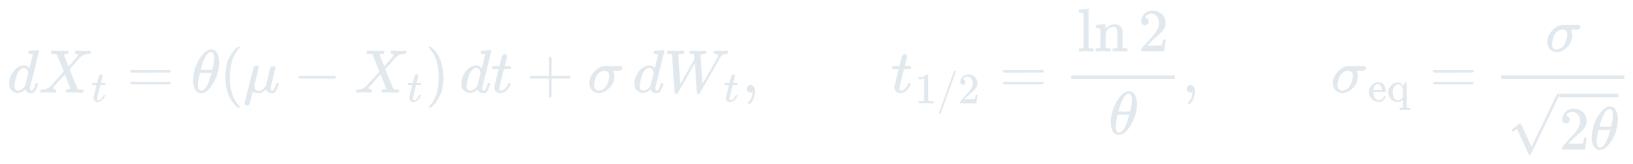
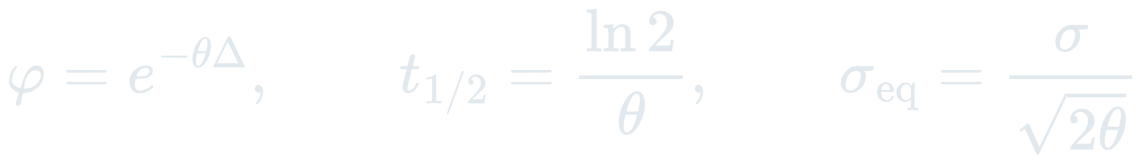
Choose profit-take π and stop-loss λ, in units of the equilibrium volatility, to maximise the Sharpe ratio of simulated exits:
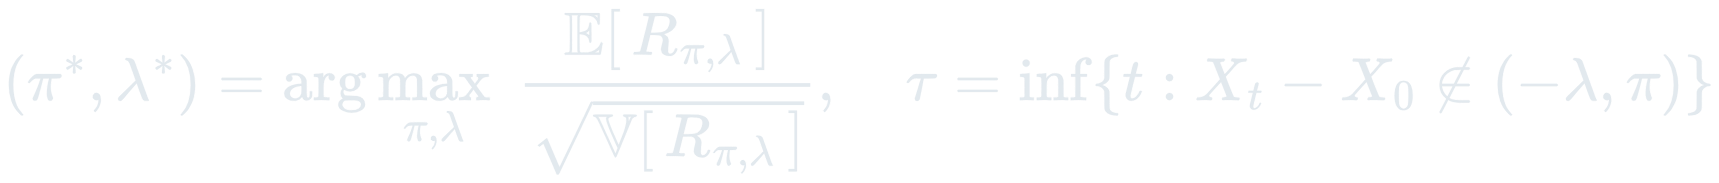
Remark. The procedure is only as good as the fit. On a 24-hour window of five-minute bars, the estimated half-life of a leveraged semiconductor ETF was not shorter than that of the same returns shuffled into a random walk.
§3Range-based estimators
High and low prices carry more information about variance than closes do. The same quantities can also be rearranged to estimate a bid–ask spread, which is where the trouble starts.
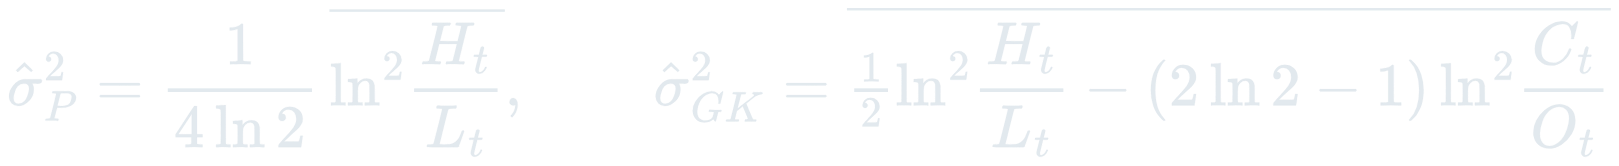
With β the sum of two one-bar squared log ranges and γ the squared log range of the two bars together,
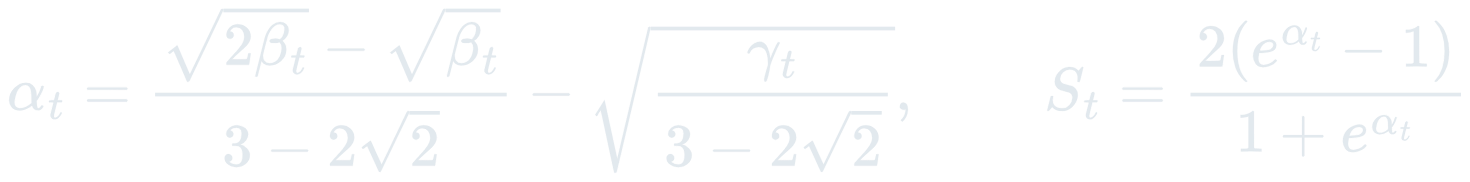
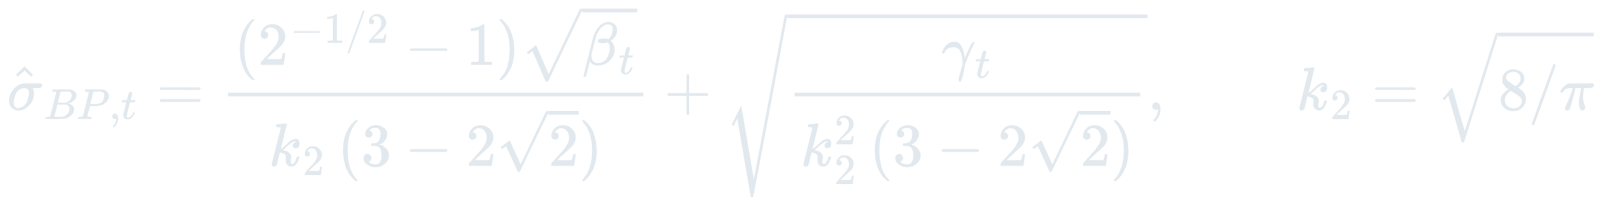
Remark. The spread estimator assumes that the only reason a two-bar range exceeds two one-bar ranges is the bid–ask bounce. In a liquid perpetual future the range is dominated by volatility.
§4The expected maximum Sharpe ratio
If N independent trials have true Sharpe ratio zero, the best of them is expected to show the value below, with γ ≈ 0.5772 the Euler–Mascheroni constant. A discovery must clear this bar, not zero.
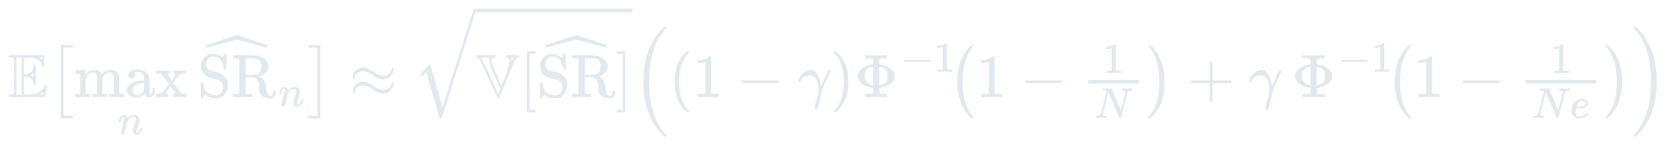
Remark. N is the number of trials actually run, including those quietly abandoned. We count trials per family in a ledger written before results are seen.
§5Price impact and the square root

One-way impact of an order of notional Q is κ·λ_H·√Q, where κ calibrates the estimator to realised fills. The Sharpe ratio of a fixed signal therefore falls monotonically with capital.
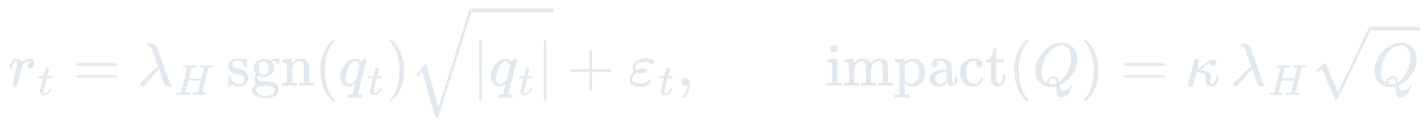
§6Sizing as an exposure dial
For a strategy with position e_t on an asset with return r_t, the benchmark holds the asset passively at the strategy’s average absolute exposure:

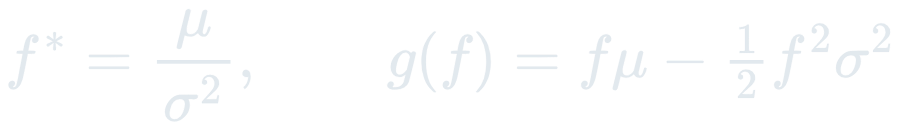
Remark. A sizing rule that scales exposure with anything correlated with recent volatility changes drawdown and absolute return without changing ΔSR. Bet-sizing from predicted probabilities correlated with exposure at −0.98.
§7Crashes after run-ups
Does a streak of gains raise the probability of a crash? We forecast a five-day drawdown in the worst decile for SOXL, TQQQ and Bitcoin, retraining every year.
Volatility alone improved on the base rate on all three assets (Brier skill +0.016 to +0.051). Adding run-up history made every forecast worse, and a single model combining every signal we had was worse still. After five or more consecutive up days the crash frequency on TQQQ was 5.9%, against 15.5% unconditionally.
Remark. Streaks of gains mark calm uptrends. Crashes follow falls and high volatility.
Notation follows the source texts where possible. Figures come from internal studies with preregistered hypotheses; live-model levels are deliberately omitted.

